Modernizing Infrastructure at Scale: How Atlassian Migrated its Global Metrics Pipeline to OpenTelemetry

For nearly a decade, Atlassian’s massive observability infrastructure relied on a legacy metrics pipeline powered by gostatsd, an open-source StatsD implementation that served as the backbone for the company’s internal monitoring. Operating across 14 global regions and managing data from approximately 100,000 hosts, the system maintained a 99.95% service-level objective (SLO) with minimal latency. However, as the software industry reached a broad consensus on the OpenTelemetry (OTel) standard, the limitations of a proprietary, aging architecture became impossible to ignore. In September 2026, Atlassian engineering leads Iris Grace Endozo, Farzad Vazirnia, and Albert Kerr detailed the successful multi-year effort to pivot their infrastructure to OpenTelemetry without disrupting the daily operations of thousands of developers.
The Technical Imperative for Change
The shift was driven by a fundamental reality of modern infrastructure: the industry has standardized on OpenTelemetry. Atlassian’s previous pipeline was essentially trapped in a silo. Gostatsd was strictly limited to UDP traffic and lacked native support for modern telemetry signals like distributed traces and logs. Consequently, whenever the OpenTelemetry community released sophisticated new features or collectors, Atlassian engineers were forced to rebuild those capabilities by hand to maintain parity.
The internal analysis was clear: the organization was losing a race against the rapid pace of open-source innovation. Sustaining a custom, manual pipeline required significant engineering overhead, as every incremental improvement in the broader observability ecosystem required bespoke integration work. The challenge, however, was not just the technical debt; it was the scale of the environment. With observability baked into thousands of services, a "rip and replace" strategy—where every team would be required to re-instrument their code—was deemed an impractical, multi-year ordeal that risked catastrophic data loss during the transition.
The Strategy: Interface Preservation
To bypass the risks of an organization-wide migration, the Atlassian team adopted a strategy of architectural encapsulation. They identified that their metrics pipeline was effectively a contract between two endpoints. On the client side, service owners expected a simple interface: send StatsD packets over UDP, and watch metrics appear in the backend. On the internal side, the pipeline handled ingestion, aggregation, and storage.
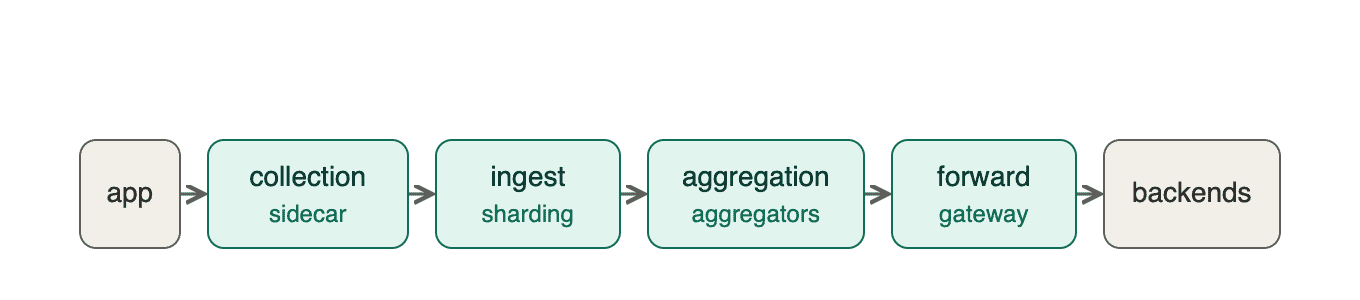
By keeping the "StatsD over UDP" interface intact, the platform team transformed a cross-organizational migration into a localized platform-team project. This allowed developers to continue using their existing instrumentation while the underlying engine was swapped out behind the scenes. The team deployed purpose-built OpenTelemetry Collector distributions across four distinct functional layers: collection, ingestion, aggregation, and forwarding. This modular design ensured that any single component could be updated, patched, or replaced without triggering a system-wide failure.
Chronology of the Transition
The migration followed a systematic, four-stage implementation plan designed to minimize operational friction.
Phase 1: Collection and Sidecar Consolidation
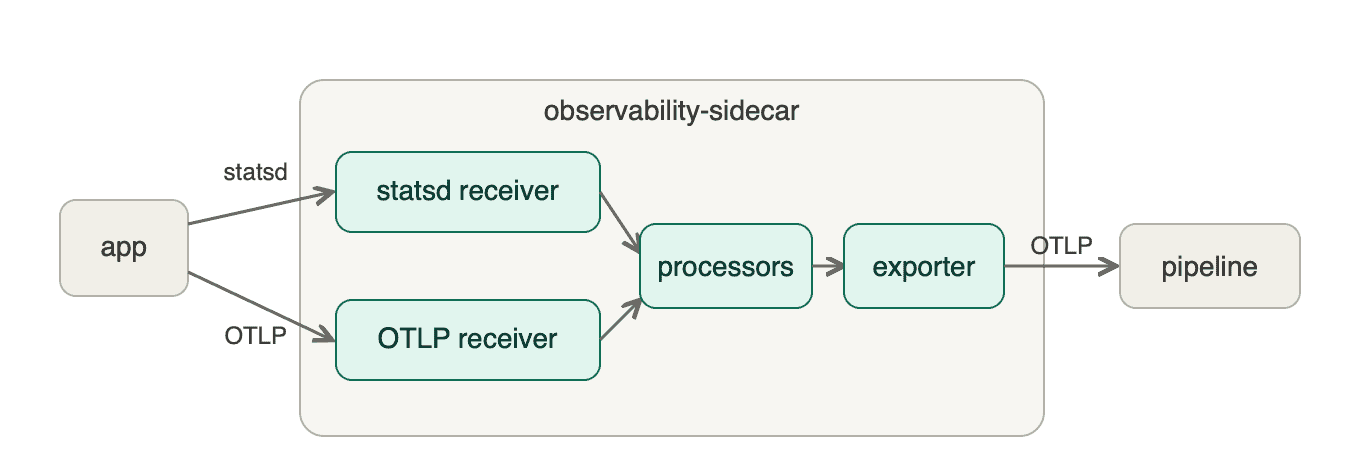
The first step involved replacing the legacy gostatsd sidecars with an Atlassian-hardened OpenTelemetry Collector distribution. Because the tracing team at Atlassian had already been utilizing the OTel Collector for years, the organization had a proven, production-ready foundation. By unifying the sidecar, the company eliminated the need to run redundant agents for metrics and traces. This consolidation resulted in a 3.9% CPU reduction on average per service across their most intensive environments, effectively cutting sidecar overhead by roughly 30% at fleet scale.
Phase 2: Intelligent Ingest Routing
Historically, Atlassian used an in-house proxy called "nomad" to handle stateful metrics aggregation. Because every datapoint for a time series had to reach the same aggregator, the legacy system relied on hashing metrics based on the service name. This created a "hot shard" problem, where the most heavily used services overwhelmed specific aggregation nodes, leading to inefficient load distribution. The new architecture utilized the OTel Collector’s loadbalancingexporter, which hashes by streamID rather than service name. This enabled a uniform distribution of load, allowing for tighter autoscaling and the elimination of manually managed "hot shard" incidents.
Phase 3: High-Performance Aggregation
The aggregation tier is the financial engine of the observability pipeline. Atlassian processes approximately 4.8 billion datapoints per minute, condensing this into 220 million points for long-term storage—a 96% reduction in data volume. Because existing community tools did not perfectly match the specific delta-aggregation needs of their users, the team developed a custom delta aggregation processor. They subsequently open-sourced this component under the Atlassian-labs GitHub repository, contributing back to the community while simultaneously reducing CPU usage by 50% compared to the legacy gostatsd aggregators.
Phase 4: Forwarding and Serverless Integration
The final hop, or "forwarder," was transitioned to a stateless metrics gateway. By leveraging upstream exporters, the team moved away from custom backend integrations. Adding a new telemetry destination now requires a simple configuration change rather than a development project. For serverless environments where sidecars are not feasible, the team developed an OTel Lambda extension, ensuring that serverless functions could interact with the new pipeline without requiring any code modifications.
Supporting Data and Economic Impact
The move to OpenTelemetry is not merely a technical upgrade; it is a significant cost-optimization initiative. Prior to the migration, the legacy gostatsd aggregators and the nomad proxy accounted for approximately 38% of total CPU requests within Atlassian’s metrics clusters. By eliminating these components and moving to a unified, community-supported codebase, the organization has realized substantial improvements in infrastructure efficiency.
Furthermore, the pipeline’s ability to drop wasteful or redundant data at the ingestion layer—the most cost-effective point in the stack—has provided a more sustainable model for handling the company’s growth. With global scale in mind, the platform team emphasized that this change was necessary to ensure the company’s observability costs remained predictable and manageable as service volume continues to climb.
Broader Industry Implications
The Atlassian case study highlights a growing trend among enterprise-scale organizations: the shift toward vendor-neutral observability standards. By aligning with OpenTelemetry, Atlassian has positioned itself to benefit from the collective intelligence of the CNCF (Cloud Native Computing Foundation) community.
Industry analysts observe that this move signals a broader maturity in the observability space. Organizations are increasingly rejecting proprietary "black box" collectors in favor of extensible, open-source pipelines that offer vendor agility. For Atlassian, the immediate benefit is a "write once, run anywhere" approach to observability, but the long-term strategic advantage lies in the ability to pivot between backends, integrate new data sources without custom engineering, and contribute to a global standard that defines how modern software behaves.
Future Outlook and Next Steps
With the core infrastructure now running on OpenTelemetry, the engineering team has turned its focus to the "shift left" strategy. The current priority is to migrate the instrumentation layer itself—moving away from vendor-specific clients and legacy StatsD libraries to the native OpenTelemetry SDKs.
As Atlassian continues to deepen its integration with the OTel ecosystem, the team plans to explore additional observability challenges, including more granular trace sampling and log correlation, using community-solved patterns. By moving from a position of maintaining legacy infrastructure to contributing to open-source innovation, Atlassian has effectively future-proofed its metrics pipeline. The project serves as a blueprint for large-scale enterprises looking to transition to modern observability standards without the disruption of a total, synchronized migration.